Certaines informations sont présentées en anglais.
À propos de moi
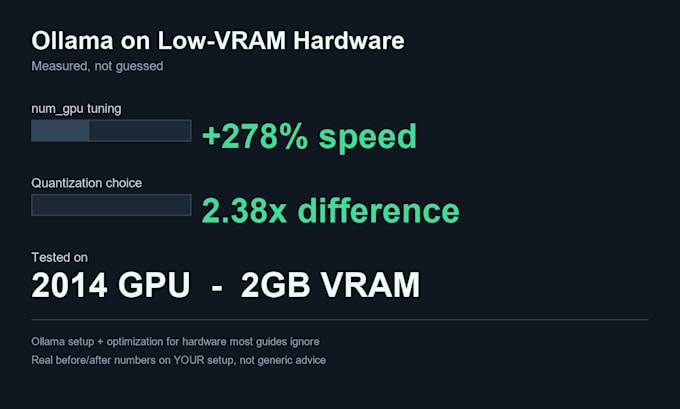
I run local LLMs on hardware most guides ignore: a 2014 GPU with 2GB of VRAM. Instead of guessing, I measure. I've found up to +278% speed just by tuning one parameter Ollama sets too conservatively by default, and a 2.38x difference between quantizations that most people never test. I help people get Ollama and local LLMs running well on the hardware they already have, whether that's an old GPU, limited VRAM, or a home lab box. You get the exact numbers I measured on your setup, not generic advice, so you know why something works, not just what to type.... Plus d’infos