Certaines informations sont présentées en anglais.
À propos de moi
Senior Data Engineer with 8+ years of experience building and optimizing large-scale distributed data pipelines.
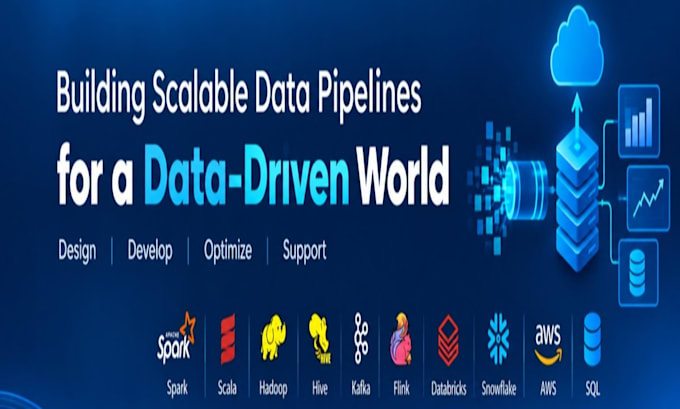
Experienced in Apache Spark, Scala, PySpark, Hive, Hadoop, SQL, and AWS, with hands-on experience processing multi-terabyte workloads and supporting production data pipelines.
My expertise includes Spark performance optimization, data skew handling, partitioning, join optimization, memory tuning, persistence and checkpointing, Hive optimization, and production troubleshooting.... Plus d’infos